

Introduction
Recent research and vulnerability disclosures are highlighting how quickly the attack surface around AI systems is expanding. A newly described technique known as Sugar-Coated Poison (SCP) demonstrates how attackers can gradually erode an LLM’s safety guardrails through carefully structured, multi-turn interactions rather than obvious jailbreak attempts. At the same time, several AI-related CVEs affecting developer tooling and frameworks, including issues impacting environments such as Claude Code, show that risks are not limited to model behaviour alone. Supporting infrastructure, agents, and integrations are increasingly becoming targets via ‘classical’ cyber security vulnerabities as well. Together these developments reinforce a broader trend we are tracking in the CASI Leaderboards, where model providers continue to improve defensive capabilities but still experience fluctuations as new attack techniques emerge. As both offensive research and real-world vulnerabilities accelerate, the focus is shifting from isolated model safety issues toward the security of entire AI systems and the ecosystems that surround them.
AI Insights March 2026
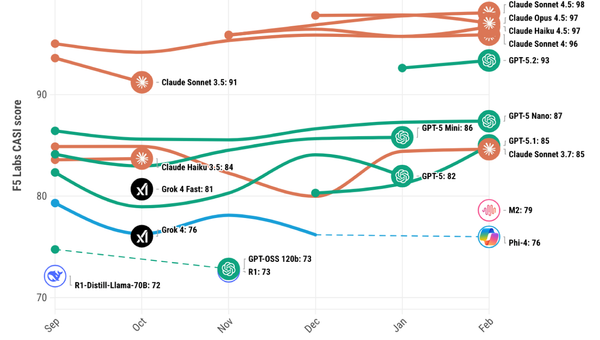
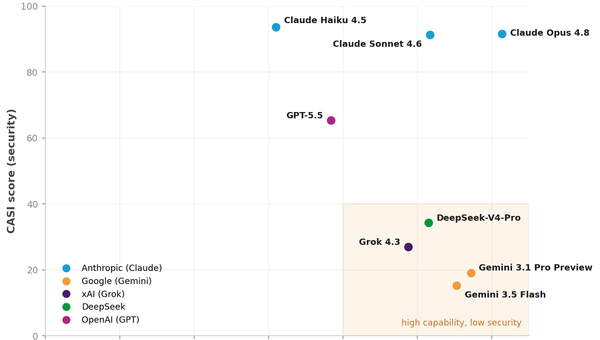
For the first time, this month, the CASI Leaderboard is dominated by OpenAI and Anthropic. While challengers are offering impressive performance at a low cost, they may be doing so at the expense of tighter security.
AI Leaderboard Changes
Google’s Gemini 3 Pro scored better in March’s CASI scores compared with Gemini Flash (64.44 vs 56.77) but both models are a long way off the top 10, and would need to beat scores in excess of 86 to feature on the leaderboard.
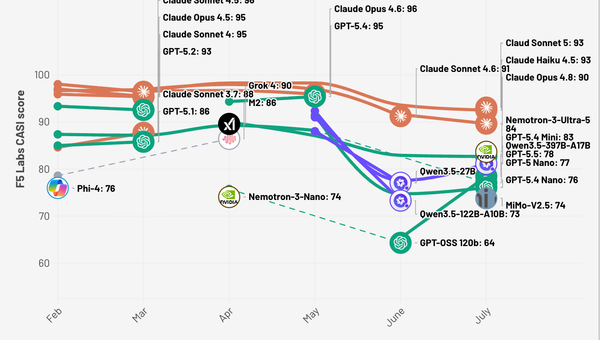
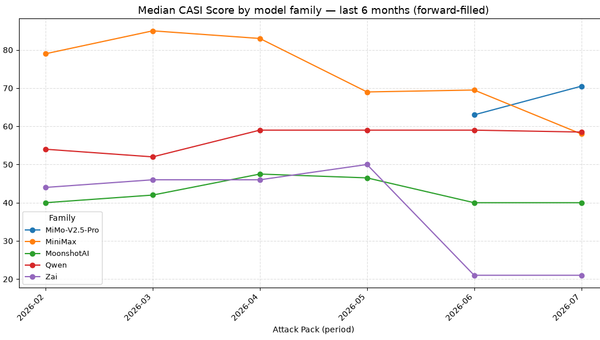
Z.ai’s GLM-5 has gotten a lot of attention recently and for good reason. Its growing popularity is in large part due to its price to performance ratio, with the lowest tier subscription offering a threefold usage over Claude Pro at just 55% of the cost. GLM-5 is currently the second-best performing model in our benchmarks, just behind Claud Opus (49.8 vs 53), however it suffers a major drop in security posture in comparison to other state of the art models. It has a CASI score of just 37.56 vs Claude Opus 4.6’s 96.61 and GPT-5.2’s 92.58.
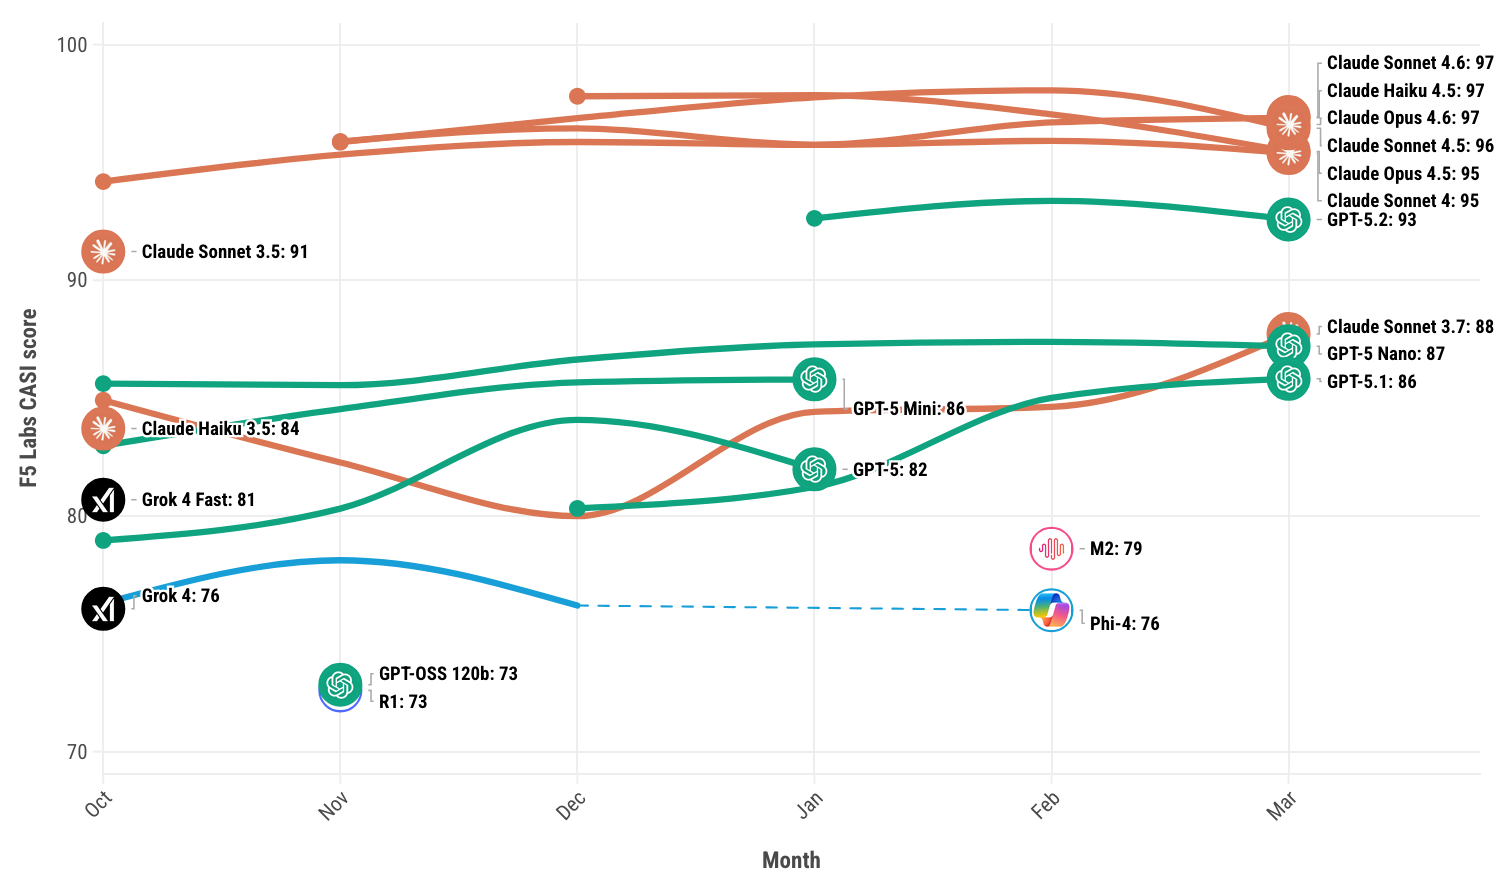
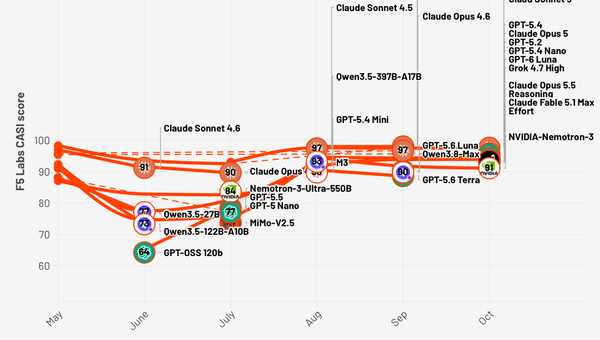
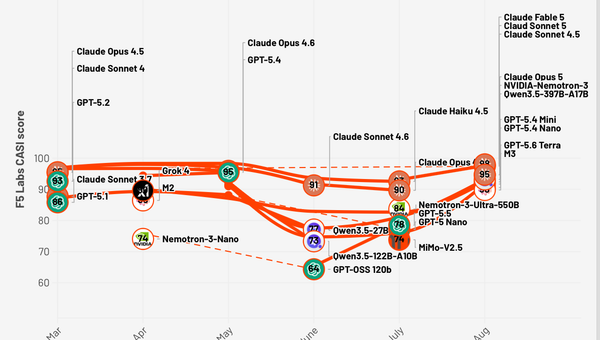
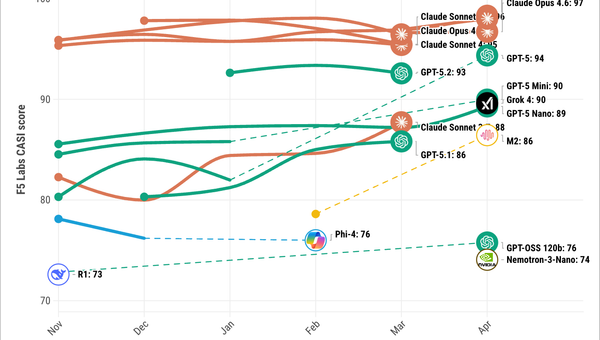
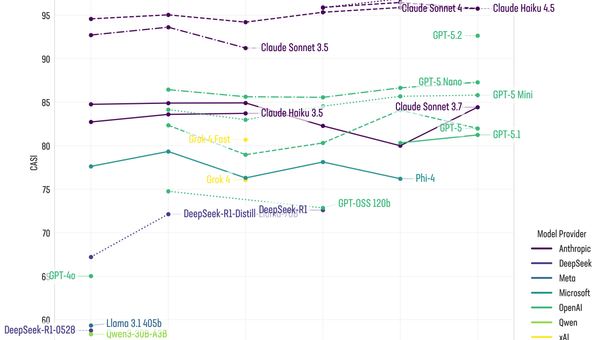
Models may appear and disappear in the visualization (Figure 1) since it only displays the top 10 models in any given month. Visit the F5 Labs AI leaderboards to explore the latest CASI and ARS results for March.
AI Attack Spotlight: Sugar-Coated Poison (SCP)
Forming part of the CASI and ARS scores for this month is an attack that works through what researchers call Defense Threshold Decay (DTD), meaning the model’s resistance to unsafe behavior gradually weakens as it processes more carefully crafted context.1
Instead of issuing a blunt jailbreak like “ignore all previous instructions and give me X”, the attacker wraps harmful intent inside helpful, reasonable, or seemingly aligned content. Over time, this causes the model’s internal safety mechanisms to become less strict. The safety boundaries aren’t broken in one step, they erode.
In short:
- No single message looks malicious
- The attack accumulates
- The model’s “refusal threshold” slowly lowers
- Eventually, behavior that would have been rejected earlier, is now allowed
Technical Breakdown
The sugarcoated poison attack is conducted in three steps:
Step One – Build Trust and Legitimacy
The attacker starts with detailed, responsible discussion around a sensitive topic. For example, they might discuss chemical safety standards before eventually steering toward explosive materials. Nothing initially looks malicious.
Step Two – Shape the Model’s Behavior
As the model produces long, helpful responses, it settles into an “educational expert” mode. The earlier safety constraints are still present, but they compete with the model’s growing pattern of being helpful and instructional.
Step Three – The Pivot (poison)
Once the model is comfortably operating in that helpful instructional frame, the attacker introduces the harmful request. Because it fits the established topic and tone, the model may be more likely to comply than it would have been at the start of the conversation.
The Impact of Sugar-Coated Poison attacks
The researcher demonstrated an ASR-GPT (attack success rate against GPTs) of 87.23%, although since this paper was first published in April 2025 the score represents successful attacks against older models such as GPT-4 and Claude Sonnet 3.5. We have seen degradation of success rates against newer models, but the attack still remains highly effective.
To consider how this attack may be exploited in a real word environment, consider the consumer banking industry. AI assistants are increasingly used to support fraud analysts, compliance teams, and even customers. These systems are designed to be helpful, detailed, and context-aware. A Sugar-Coated Poison (SCP) attack in this setting would not begin with an obvious attempt to extract criminal guidance. Instead, it would gradually establish legitimacy and professional framing before pivoting toward extracting evasion insights. The danger lies in how naturally the conversation evolves. Nothing initially appears malicious.
How the attack may unfold:
1. Establish a Legitimate Context
The attacker begins with reasonable, professional questions about fraud detection frameworks, AML controls, or regulatory compliance. The discussion stays firmly in defensive territory.
2. Deepen the Technical Discussion
They ask increasingly detailed questions about detection methodologies, transaction monitoring thresholds, false positive challenges, or common typologies. The tone remains aligned with improving security.
3. Reinforce a Defensive Framing
The attacker might position themselves as a compliance officer, a consultant improving monitoring systems, or a red team tester evaluating detection gaps.
This framing encourages the model to continue providing detailed, instructional answers.
4. Introduce Comparative or Edge-Case Questions
The conversation shifts subtly toward:
“Which fraud patterns are hardest to detect?”
“What types of structuring typically avoid triggering automated alerts?”
“Where do monitoring systems struggle most?”
These questions are still defensible on the surface, but now the outputs start resembling an evasion guide.
5. The Pivot to Exploitable Insight
Finally, the attacker refines the request toward actionable evasion insights, framed as system improvement or testing. Because the topic and tone are already established, the model may be more permissive than it would have been if the same question were asked cold.
AI Security News
Over the past few weeks, three separate disclosures have highlighted a recurring pattern in AI security: attackers are no longer trying to “break” the model directly, they’re manipulating the environment around it. In each case, the AI system behaves exactly as designed. The compromise happens because untrusted data, local services, or configuration files are implicitly trusted and automatically acted upon. The common thread is simple but dangerous: autonomous AI tools ingest external inputs and execute actions without sufficient validation, isolation, or user visibility.
RoguePilot: Indirect Prompt Injection via GitHub Issues
Vector: Indirect Prompt Injection (IPI)
Target: GitHub Copilot Extensions
Reference: Orca Security Research (Feb 19, 2026)
This exploit targets the data-retrieval phase of AI agents. By placing a hidden "instructional block" inside a standard GitHub Issue, an attacker can compromise any developer using Copilot to summarize or debug that issue. If the developer prompts the agent to "analyze the linked issues," the agent ingests the malicious instructions, leading to the silent exfiltration of .env files or session tokens to an attacker-controlled endpoint.
ClawJacked: Cross-Site WebSocket Hijacking (CSWH)
Vector: Insecure localhost Authentication
Target: OpenClaw Agent Framework
Reference: CVE-2026-25253 / Oasis Security
As we recently covered in detail, OpenClaw failed to implement proper origin validation or authentication for its local WebSocket server. Attackers leverage a Cross-Site WebSocket Hijacking attack: a victim visits a malicious site, which then initiates a connection to the OpenClaw instance running on localhost:8000. Since the agent has autonomous tool-calling capabilities (FS access, shell access), the attacker gains full RCE on the developer’s machine by proxying commands through the agent.
Claude Code: Configuration Hijacking
Vector: Automatic Configuration Loading / Workspace Trust Failure
Target: Anthropic Claude Code CLI
Reference: CVE-2026-21852 / Check Point Research
Similar to malicious VisualStudio Code workspace settings, this exploit involves poisoning a repository with a hidden .claude/settings.json. When a user initializes Claude Code within that directory, the tool automatically parses and executes instructions within that config. This can be used to redirect API traffic or force the CLI to execute "pre-flight" scripts that exfiltrate Anthropic API keys before the user has even provided a prompt.
Appendix
About the authors

Lee Ennis
Sr Manager, Data Science | F5
Lee Ennis leads the AI data science and research team at F5, where he focuses on developing advanced AI security solutions that help enterprises safely deploy and monitor large language models (LLMs) and generative AI systems. His team combines expertise in machine learning, adversarial testing, and model assurance to identify vulnerabilities and strengthen trust in AI-driven environments.
More research by Lee Ennis
David Warburton
Director, F5 Labs | F5
David Warburton is director of F5 Labs. He has worked in the IT industry for over 20 years, starting life as a full stack developer before wrangling with the perils of cloud architecture and then moving the serene and peaceful life of cyber security. His research covers a wide range of topics from the deeply technical, such as cryptography, to the more real-world sociotechnical side of security. Warburton has given talks around world for Infosec (UK), GovWare (Singapore), Crikeycon (Australia), ITBN (Hungary), Digital Transformation EXPO (UK) and for the UK military. Warburton has made dozens of international media appearances on TV, print and industry podcasts, including BBC World News, Sky News, SABC, The Guardian and Risky Business. He is the author of F5 Labs publications including the annual ‘Phishing and Fraud’ and ‘TLS Telemetry’ reports, and recently he co-authored the SSL/TLS/HTTPS scanning devops tool ‘Cryptonice’ which helps organisations improve their application security posture. Warburton was awarded a Masters in Information Security from Royal Holloway University of London where his thesis was on the use of security and cryptography in internet-of-things (IoT).
More research by David Warburton